
All articles
21 posts, generated from Markdown in the content repository.

Gateway API in Production: Migrating Off Retired Ingress-NGINX at Enterprise Scale
title: "Gateway API in Production: Migrating Off Retired Ingress-NGINX at Enterprise Scale" date: 2026-09-17 tags: [Kubernetes, Gateway API, Ingress, Networking, Envoy, Cilium, Istio, Platform Engineering, GitOps, Mul…

MCP at Production Scale: Gateway Architecture, Tool-Level RBAC & Securing AI Agent Infrastructure on Kubernetes
title: "MCP at Production Scale: Gateway Architecture, Tool-Level RBAC & Securing AI Agent Infrastructure on Kubernetes" date: 2026-09-16 tags: [Kubernetes, MCP, AI Agents, AI Infrastructure, AI Gateway, Security, OAu…

OpenTelemetry at Scale: Collector Gateways, Tail-Based Sampling & Trace-Log-Metric Correlation in Production
title: "OpenTelemetry at Scale: Collector Gateways, Tail-Based Sampling & Trace-Log-Metric Correlation in Production" date: 2026-09-15 tags: [Kubernetes, OpenTelemetry, Observability, Prometheus, Grafana, Tempo, Loki,…

CI/CD at Enterprise Scale: Actions Runner Controller, Ephemeral Runners, and Distributed BuildKit Caching on Kubernetes
title: "CI/CD at Enterprise Scale: Actions Runner Controller, Ephemeral Runners, and Distributed BuildKit Caching on Kubernetes" date: 2026-09-14 tags: [Kubernetes, CI/CD, GitHub Actions, ARC, Platform Engineering, Bu…

Kubernetes Runtime Security at Scale: Falco, Tetragon, and eBPF-Native Threat Detection
title: "Kubernetes Runtime Security at Scale: Falco, Tetragon, and eBPF-Native Threat Detection" date: 2026-09-12 tags: [Kubernetes, eBPF, Falco, Tetragon, Runtime Security, DevSecOps, Cilium, CNCF] cover: ../images/f…

Ray on Kubernetes: KubeRay, Gang Scheduling, and Distributed Training/Serving at Scale
title: "Ray on Kubernetes: KubeRay, Gang Scheduling, and Distributed Training/Serving at Scale" date: 2026-09-11 tags: [Kubernetes, Ray, KubeRay, GPU, AI Infrastructure, Distributed Training, LLMOps, Kueue] cover: ../…
Prometheus + Thanos at Scale: Taming Cardinality Explosions and Global Query Federation
Daily DevOps Mentor — 2026-09-10 Prometheus won the metrics war on a simple bet: a pull-based, dimensional, label-oriented time-series model with a query language expressive enough for alerting and dashboards, wrapped…
Kubernetes DNS at Scale: CoreDNS, NodeLocal DNSCache, and the 5-Second SERVFAIL Bug
Daily DevOps Mentor — 2026-09-09 DNS is the one dependency every workload has whether it knows it or not. A pod that never opens a socket to another Service still resolves kubernetes.default.svc.cluster.local on start…
KEDA at Production Scale: Event-Driven & GPU-Aware Autoscaling from Queue Depth to Inference Load
Daily DevOps Mentor — 2026-09-08 The Horizontal Pod Autoscaler has one structural blind spot that every platform team eventually collides with: it can only scale on resource metrics (CPU, memory) or a custom/external…

Zero-Trust Cloud Credentials: AWS IRSA vs EKS Pod Identity vs Azure Workload Identity at Multi-Cloud Scale
title: "Zero-Trust Cloud Credentials: AWS IRSA vs EKS Pod Identity vs Azure Workload Identity at Multi-Cloud Scale" date: 2026-09-07 tags: [kubernetes, aws, azure, iam, security, devsecops, multi-cloud] Every fleet th…
Production AI Gateway Architecture: Multi-Model LLM Routing, Token-Aware Rate Limiting & Failover at Scale
Daily DevOps Mentor — 2026-09-04 Every platform team that shipped more than one LLM-backed feature has independently reinvented the same piece of infrastructure: a proxy layer sitting between application code and mode…
Progressive Delivery at Scale: Argo Rollouts, Automated Canary Analysis & Multi-Cluster Blue/Green Deployments
Daily DevOps Mentor — 2026-09-03 A standard Kubernetes Deployment rolling update is a blunt instrument: it shifts traffic to new pods based on readiness probes passing, not on whether the new code is actually behaving…
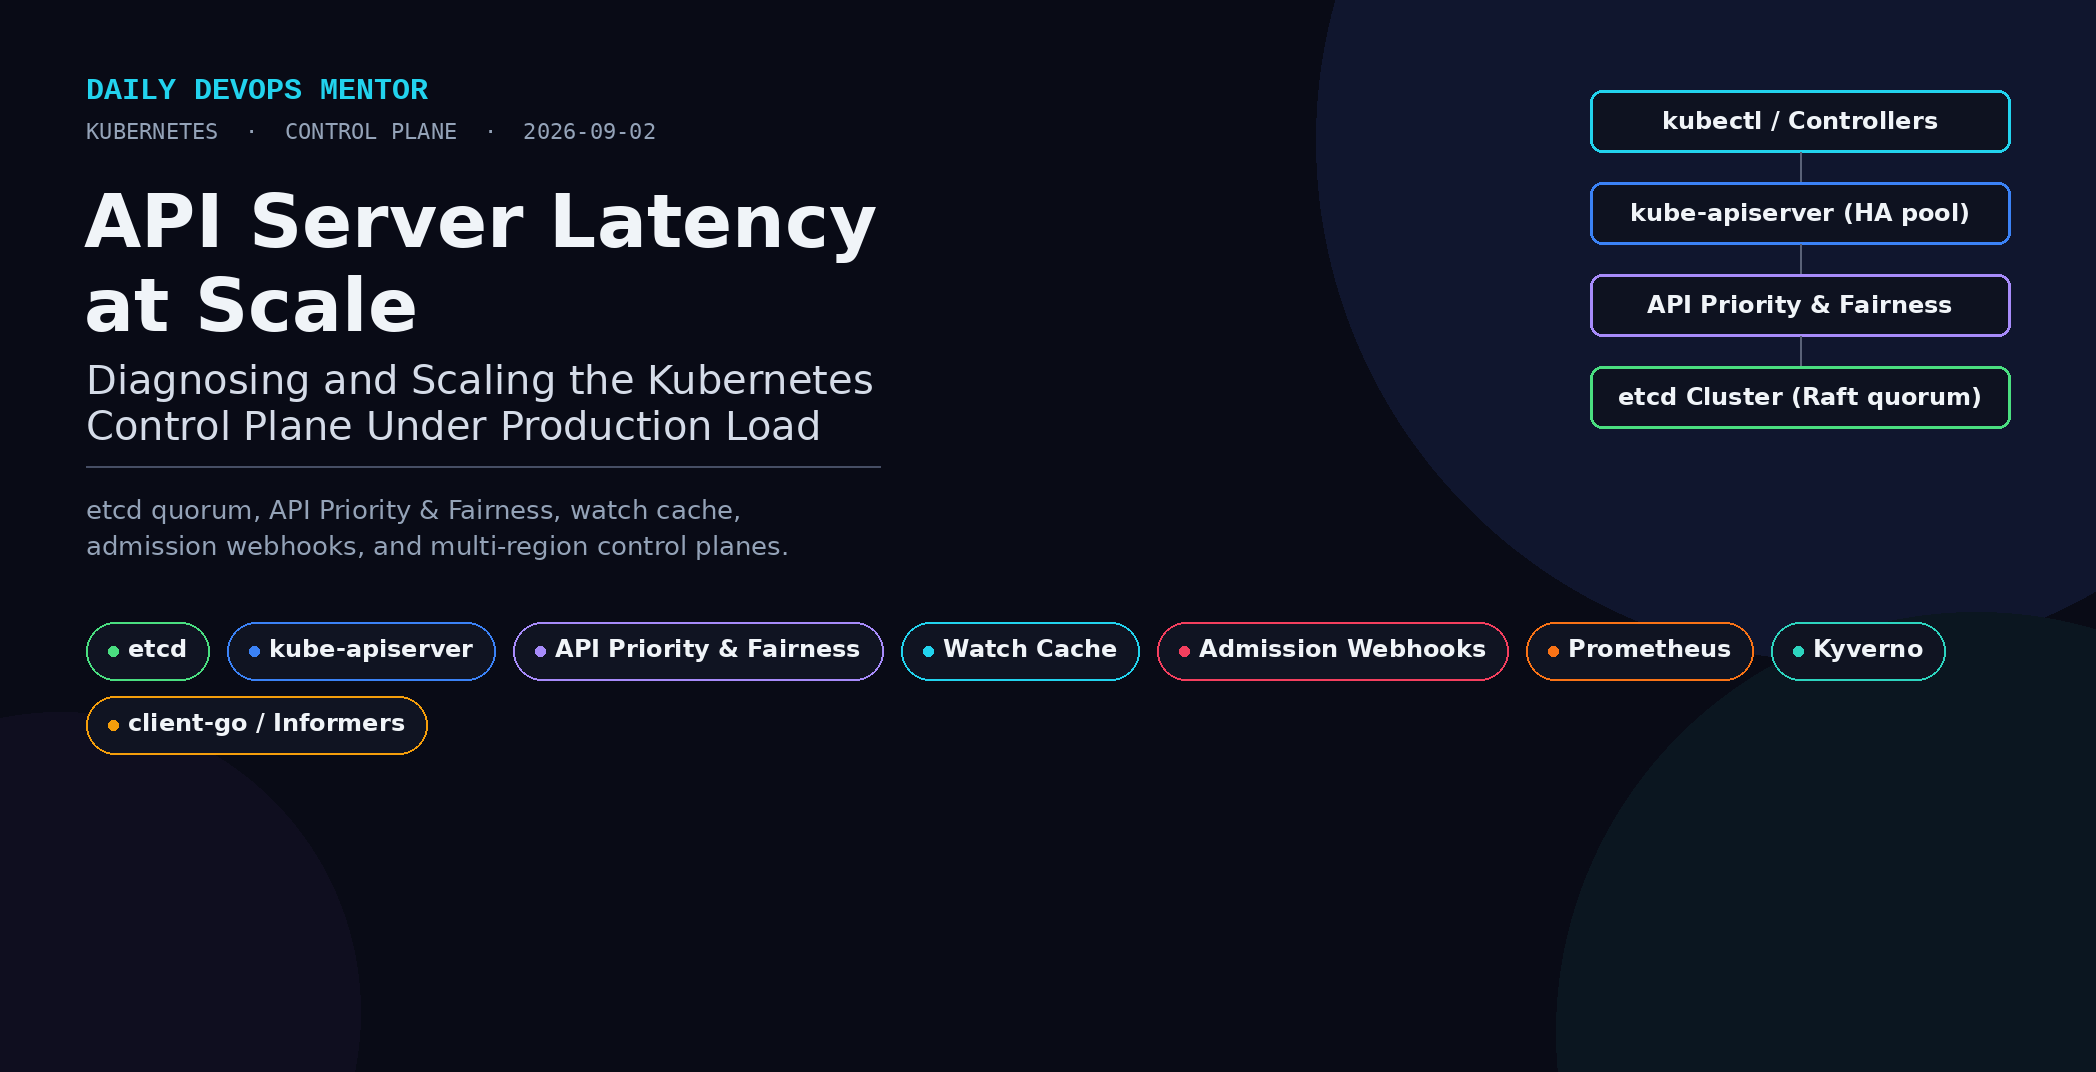
Kubernetes API Server Latency at Scale: Diagnosing and Scaling the Control Plane
Daily DevOps Mentor — 2026-09-02 Every other piece of the platform — schedulers, controllers, service meshes, GitOps reconcilers, the AI inference platforms covered in recent sessions — assumes one thing is fast and a…
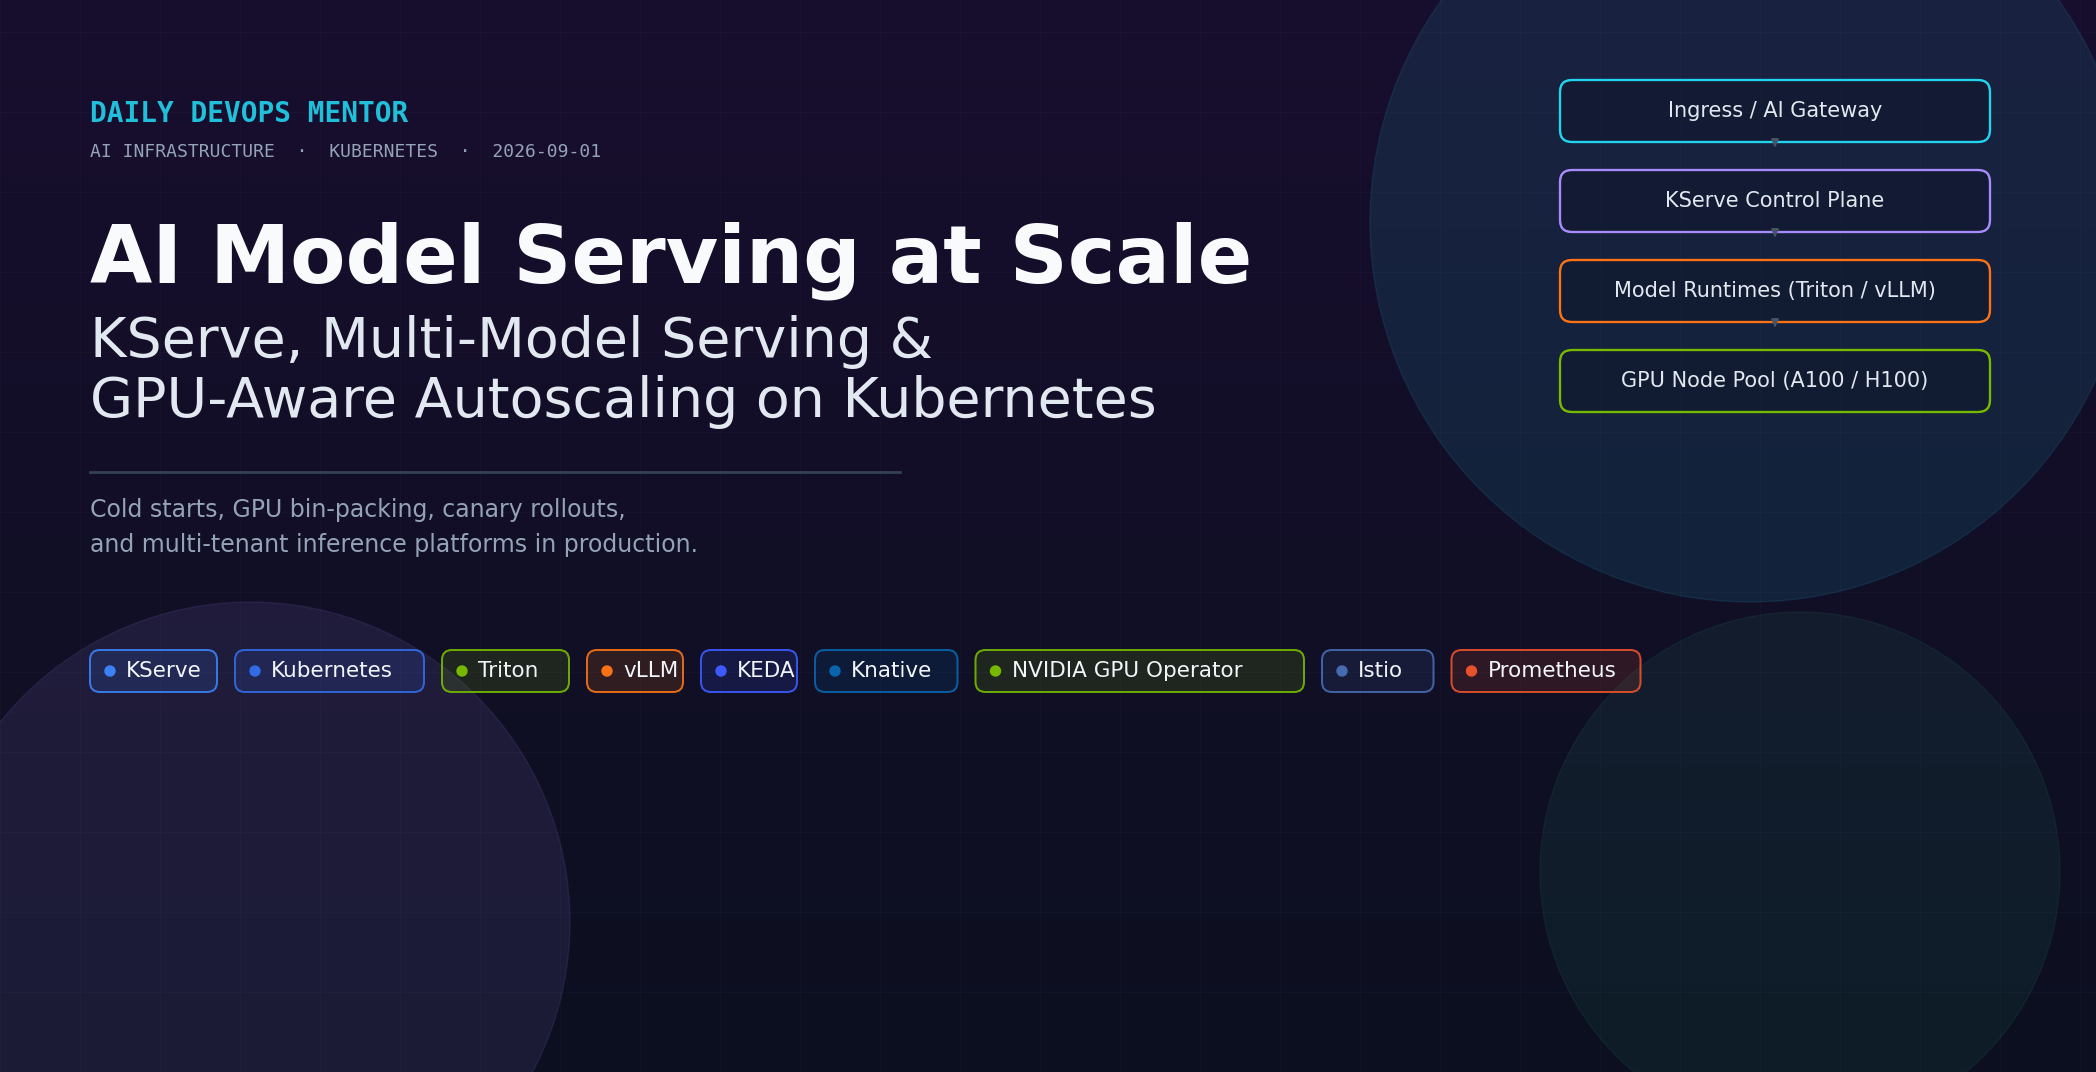
AI Model Serving at Scale: KServe, Multi-Model Serving & GPU-Aware Autoscaling on Kubernetes
Daily DevOps Mentor — 2026-09-01 Every AI infrastructure team eventually hits the same wall: training gets a model to "works in a notebook," but serving it to production traffic — with SLOs, multi-tenant isolation, co…
Service Mesh Migration: Sidecar to Istio Ambient Mesh at Scale
Daily DevOps Mentor — 2026-08-31 Service mesh exists because mutual TLS, retries, circuit breaking, fine-grained authorization, and golden-signal telemetry are cross-cutting concerns that no team wants re-implemented…
GPU Node Exhaustion: Multi-Tenant GPU Scheduling with DRA, MIG, Time-Slicing, and KAI Scheduler
Daily DevOps Mentor — 2026-08-27 GPU scheduling on Kubernetes exists because the default scheduler was built for a world of fungible, integer-divisible CPU and memory — and a GPU is neither fungible nor integer-divisi…
ArgoCD at Scale: GitOps Reconciliation, Sync Failures, and Multi-Cluster Progressive Delivery
Daily DevOps Mentor — 2026-08-26 Argo CD exists because CI pipelines and CD pipelines have fundamentally different failure modes, and bolting deployment onto a CI script eventually breaks at fleet scale. CI is imperat…
Taming AI Inference Latency Spikes with vLLM, KServe & Distributed Serving on Kubernetes
Every hyperscaler that ships LLM products (OpenAI, Anthropic, Google, Microsoft, Amazon, NVIDIA-powered neoclouds) faces the same core operational problem: GPU inference is expensive, latency-sensitive, and bursty, wh…
Software Supply Chain Security — Sigstore, Cosign, SLSA Provenance, and Admission-Time Enforcement on Kubernetes
Software supply chain security is the discipline of proving — cryptographically, not by policy document — that the artifact running in production is the exact artifact your CI pipeline built, from source you reviewed,…
Karpenter — Next-Generation Kubernetes Cluster Autoscaling (AWS)
Karpenter is a Kubernetes-native, high-performance node lifecycle manager originally built by AWS, now a CNCF project with providers for AWS, Azure, and (community) GCP/bare-metal. It replaces the Cluster Autoscaler (…
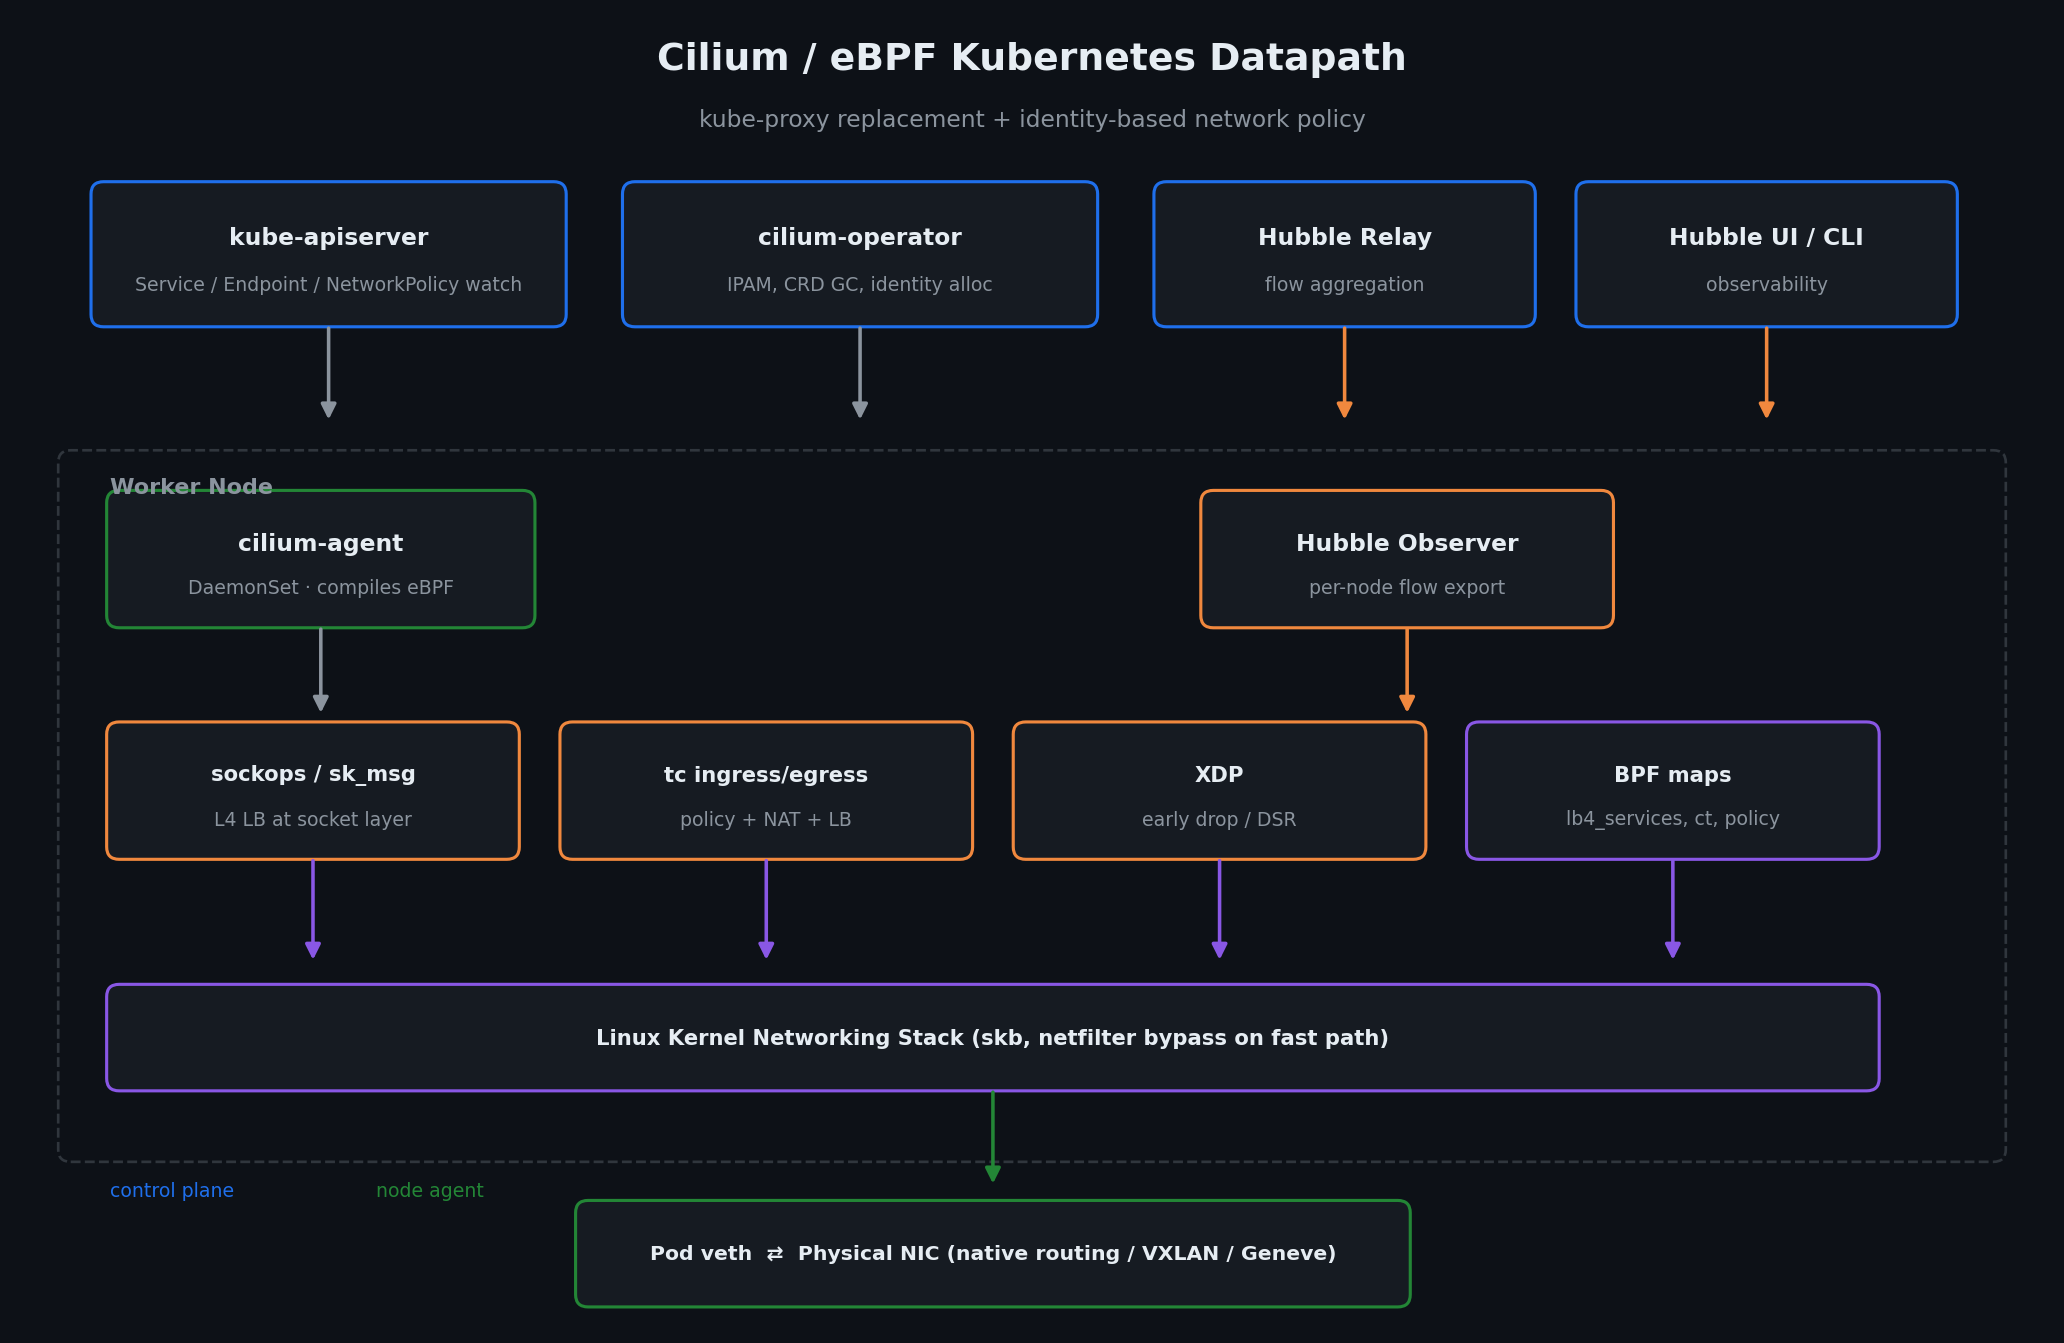
Cilium & eBPF — Replacing kube-proxy for Kubernetes Networking at Scale
Cilium is a CNCF-graduated Container Network Interface (CNI) plugin built on eBPF (extended Berkeley Packet Filter) that replaces the traditional iptables/IPVS-based Kubernetes service datapath with programs that run…